Summary: RAG chatbots usually stall at proof of concept (PoC) because nobody can say how often they are right. Getting to production takes prepared documents, sensible chunking, an evaluation set of real questions with known answers, a defined "I don't know" behavior, access control, and an improvement loop after launch.
Contents
- Why do RAG chatbots demo well and then stall at PoC?
- Where does RAG accuracy break down?
- How should documents be prepared before loading them?
- How do you build an evaluation set?
- What should the chatbot do when it does not know?
- What does the operation loop look like after launch?
- When is a RAG chatbot not ready for production?
1. Why do RAG chatbots demo well and then stall at PoC?
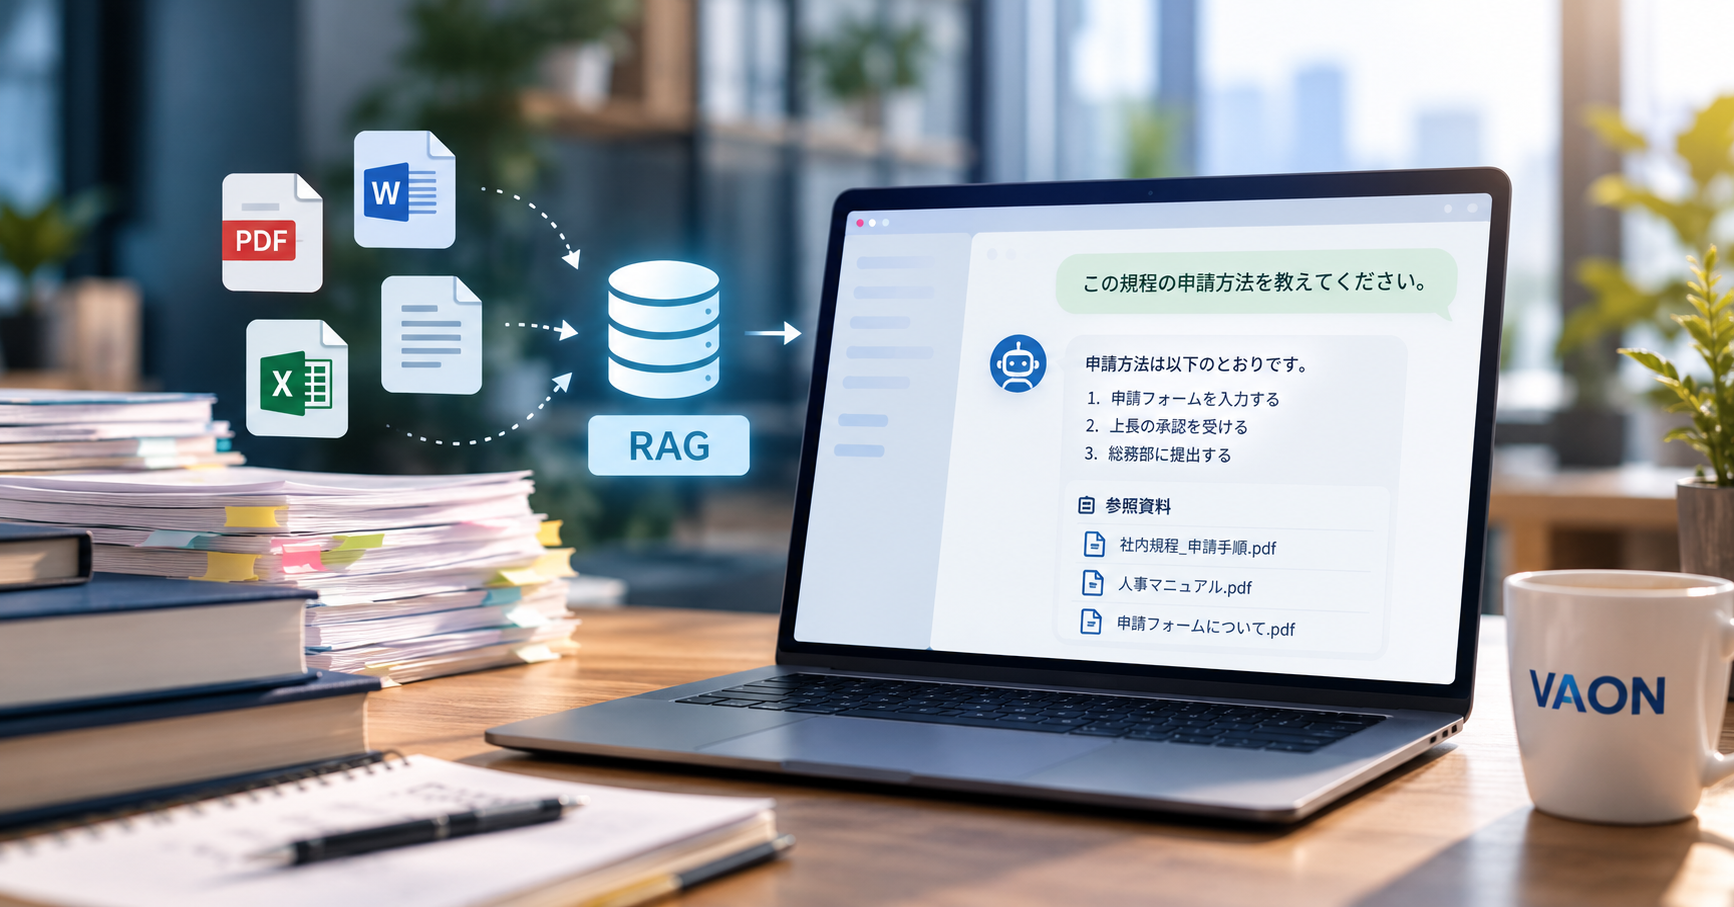
A RAG chatbot (it retrieves relevant passages from your documents and lets an AI write the answer from them) stalls at PoC because the demo uses a handful of pre-selected questions, while real users ask things nobody planned for. Once staff start using it, a few wrong answers get out, and nobody can answer the question "how often is it right?"
Without a number, the approval board has nothing to sign. The project owner is left fixing wrong answers one at a time by feel, never sure whether a fix broke something else. The project drifts for a few months and sinks.
Swapping the AI model is usually not the first move. The first move is setting a yardstick, then fixing the stage that is actually failing.
2. Where does RAG accuracy break down?
RAG accuracy breaks in one of two places: retrieval pulls the wrong passage, or the right passage is found and the AI words the answer wrongly. The two need different fixes, so you have to tell them apart before changing anything.
| Symptom | Common cause | Direction |
|---|---|---|
| Answer comes from the wrong or an outdated document | Several versions of a document sit in the index; no effective date | Clean the document set; add version and effective date |
| A passage that exists is not found | Chunking cuts an idea in half; the question uses different words from the document | Chunk by structure; combine keyword and semantic search |
| Tables and forms return wrong figures | Image-only PDFs, or tables shredded during parsing | Convert tables to a structured form before loading |
| Right passage, wrong answer | The passage is cut off; the question needs several passages | Re-chunk; limit how far the AI may infer |
| Confident answer where the documents say nothing | No "don't know" rule | Design a threshold and a refusal wording (section 5) |
The table shows that most symptoms start in documents and retrieval. Tuning the prompt only addresses the rest.
3. How should documents be prepared before loading them?
Documents should be selected, cleaned, and labeled before loading, because a RAG chatbot is only as good as what it reads. This step tends to be trimmed to hit a PoC deadline, and the result is a chatbot reading junk.
- Pick the right sources. One source of truth per topic. Drafts, old versions, and copies forwarded by email stay out.
- Handle difficult formats. Scanned PDFs, tables with merged cells, text inside images, and slides that contain only diagrams are easy to misread. Open each type and look at what the system actually extracts.
- Chunk by meaning. Splitting by headings and clauses usually beats splitting at a fixed character count. A clause cut in half produces a half-right passage.
- Attach metadata. Version, effective date, department, confidentiality level. This helps drop old documents and is the base for access control.
- Name an owner. When a policy changes, who updates the index? Without a name, the chatbot answers from an expired policy.
Item 5 is the easiest to forget, and it is why a chatbot that was right at launch turns wrong a few months later.
4. How do you build an evaluation set?
An evaluation set should hold 50 to 100 real user questions, each with an answer and source document confirmed by someone in the business. This is how VAON recommends running a chatbot PoC, because it turns "seems fine" into a number someone can sign off on.
How to build it:
- Take questions from reality. Internal Q&A emails, call-center history, what staff keep asking the admin team. Do not let the project team invent them, because they will ask the way the documents are written.
- Mix types. Single-fact lookups, questions that need two documents, questions phrased differently from the source, and questions the documents cannot answer.
- Let business staff write the answers. Not the engineers.
- Fix the pass criteria before running. For example, which success rate allows go-live. Customer and VAON agree on the number; there is no universal threshold.
When you measure, separate three indicators: did retrieval find the right passage, was the answer correct, and for unanswerable questions did the chatbot refuse correctly. Only then do you know whether to fix documents or fix answering.
An example of how to state results. VAON ran an AI document-processing automation project for a Japanese web-services company (anonymized): manual work fell 20 to 35%, and accuracy was 85 to 92%. This was document processing, not a RAG chatbot, so it is not a benchmark for chatbots. What is worth borrowing is the form: a range, tied to a specific dataset, not one round number claimed for every case. Report your chatbot the same way.
5. What should the chatbot do when it does not know?
A RAG chatbot should say plainly that it found nothing and point to a person or document, instead of guessing. "I could not find that; please ask HR" does far less harm than a wrong answer delivered in a confident voice.
This has to be designed from the start:
- Set a threshold: when retrieved passages are not relevant enough, the chatbot declines rather than answers.
- Show sources: each answer names the document and section used, so users can check.
- Offer a handoff: the refusal says where to ask next.
- Put unanswerable questions in the evaluation set, so you measure refusing at the right time too.
Access control belongs here too. The chatbot should search only documents the asker may see, and the filtering must happen at the retrieval step, not just in the interface. A chatbot that answers correctly but shows internal documents to the wrong person is still unusable. Poisoned documents carrying hidden instructions are a separate risk, covered in prompt injection and attacks on RAG systems. For the data terms of a chatbot service, see how RAG differs from training and what to check.
6. What does the operation loop look like after launch?
After launch, the loop has four repeating steps: collect real questions, review wrong or refused answers, fix the documents or retrieval, and rerun the evaluation set. Without this loop, accuracy slowly decays as documents change.
- Collect. Log real user questions and a "helpful / not helpful" rating.
- Review. Weekly or monthly, a business owner reads the low-rated and refused answers.
- Fix the right spot. Missing document: add it. Outdated document: replace it. Bad chunking: re-chunk. Changing the model is usually the last option.
- Remeasure. Add the new questions to the evaluation set and rerun everything to confirm one fix did not break another.
Real questions are your most valuable data. After a few rounds, the evaluation set reflects your users better than anything written during the PoC.
7. When is a RAG chatbot not ready for production?
A RAG chatbot is not ready for production when the source documents are unstable, nobody owns them, or a wrong answer has consequences and no one reviews it. In that case the first job is fixing the documents, not the chatbot.
A few situations deserve extra care: legal clauses, medical content, or anything that drives a financial decision directly. RAG reduces fabricated answers but does not remove them, so a person should confirm this content before it reaches users. If data may not leave the internal network, look at a different design; see RAG chatbots in a closed network. VAON's AI work is described on the AI and automation service page.
Is your RAG chatbot stuck at PoC and you are not sure where to start fixing it? Bring a few dozen real questions and some sample documents to the first call. VAON's CEO joins, no obligation. Book a free 60-minute consultation
References
- Lewis, P. et al., Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks, NeurIPS 2020: https://arxiv.org/abs/2005.11401